🧠
2.8T MoE Architecture
896 expert subnetworks with only 16 activated per token — massive capacity, efficient compute. The largest open-weight model ever released.
Moonshot AI · Launched July 16, 2026
The world's first open 3T-class model — 2.8 trillion parameters, a 1-million-token context window, and native vision. Open weights since July 27, 2026, and available on Moonshot's API, Amazon Bedrock and 15+ other providers at $3 / $15 per million tokens.
Kimi K3 is the newest flagship AI model from Moonshot AI, officially launched on July 16, 2026. It is the largest open-weight model ever released — a 2.8-trillion-parameter mixture-of-experts system that routes each token through just 16 of its 896 specialized experts, delivering frontier intelligence at practical cost. (Many people also search for it as “Kimi 3.0” — the official name is Kimi K3. Full specifications below.)
K3 introduces a 1-million-token context window, native image and video understanding, and two architectural breakthroughs — Kimi Delta Attention and Attention Residuals — that make it up to 6.3× faster at long contexts and ~2.5× more scaling-efficient than Kimi K2. On Artificial Analysis's current index (v4.3.2) it scores 44, #3 among large open-weight models. Newer closed models such as Claude Opus 5.5 and GPT-6 Astra score higher, but K3 remains one of the strongest models you can download and self-host.
The weights have been public on Hugging Face since July 27, 2026 under the custom Kimi K3 License, and the model is served by Moonshot's API, Amazon Bedrock (since September 18) and 15+ other providers. See our latest guides for pricing, hardware and head-to-head comparisons.
Watch · Official demo
In a single 48-hour autonomous run, K3 built, optimized and verified a working chip using open-source EDA tools. This video was also written, shot and rendered by K3.
48 hrs
fully autonomous run
3.981 mm²
Nangate 45nm · 100 MHz
8,721 tok/s
decode throughput in sim
1.46M
standard cells placed
SOURCE: MOONSHOT AI — KIMI K3 LAUNCH BLOG
Benchmarks · Official + independent
Kimi K3 ranks #1 on 4 of 8 real-world agentic benchmarks (Program Bench, SWE Marathon, SpreadsheetBench 2, Automation Bench — plus BrowseComp), and is the only open model within striking distance of GPT-5.6 Sol and Claude Fable 5. Moonshot itself notes K3 still trails those two overall — and independent testers at Artificial Analysis now score it 44 on index v4.3.2, #3 among large open-weight models (the July launch score of 57 was on an older index version).
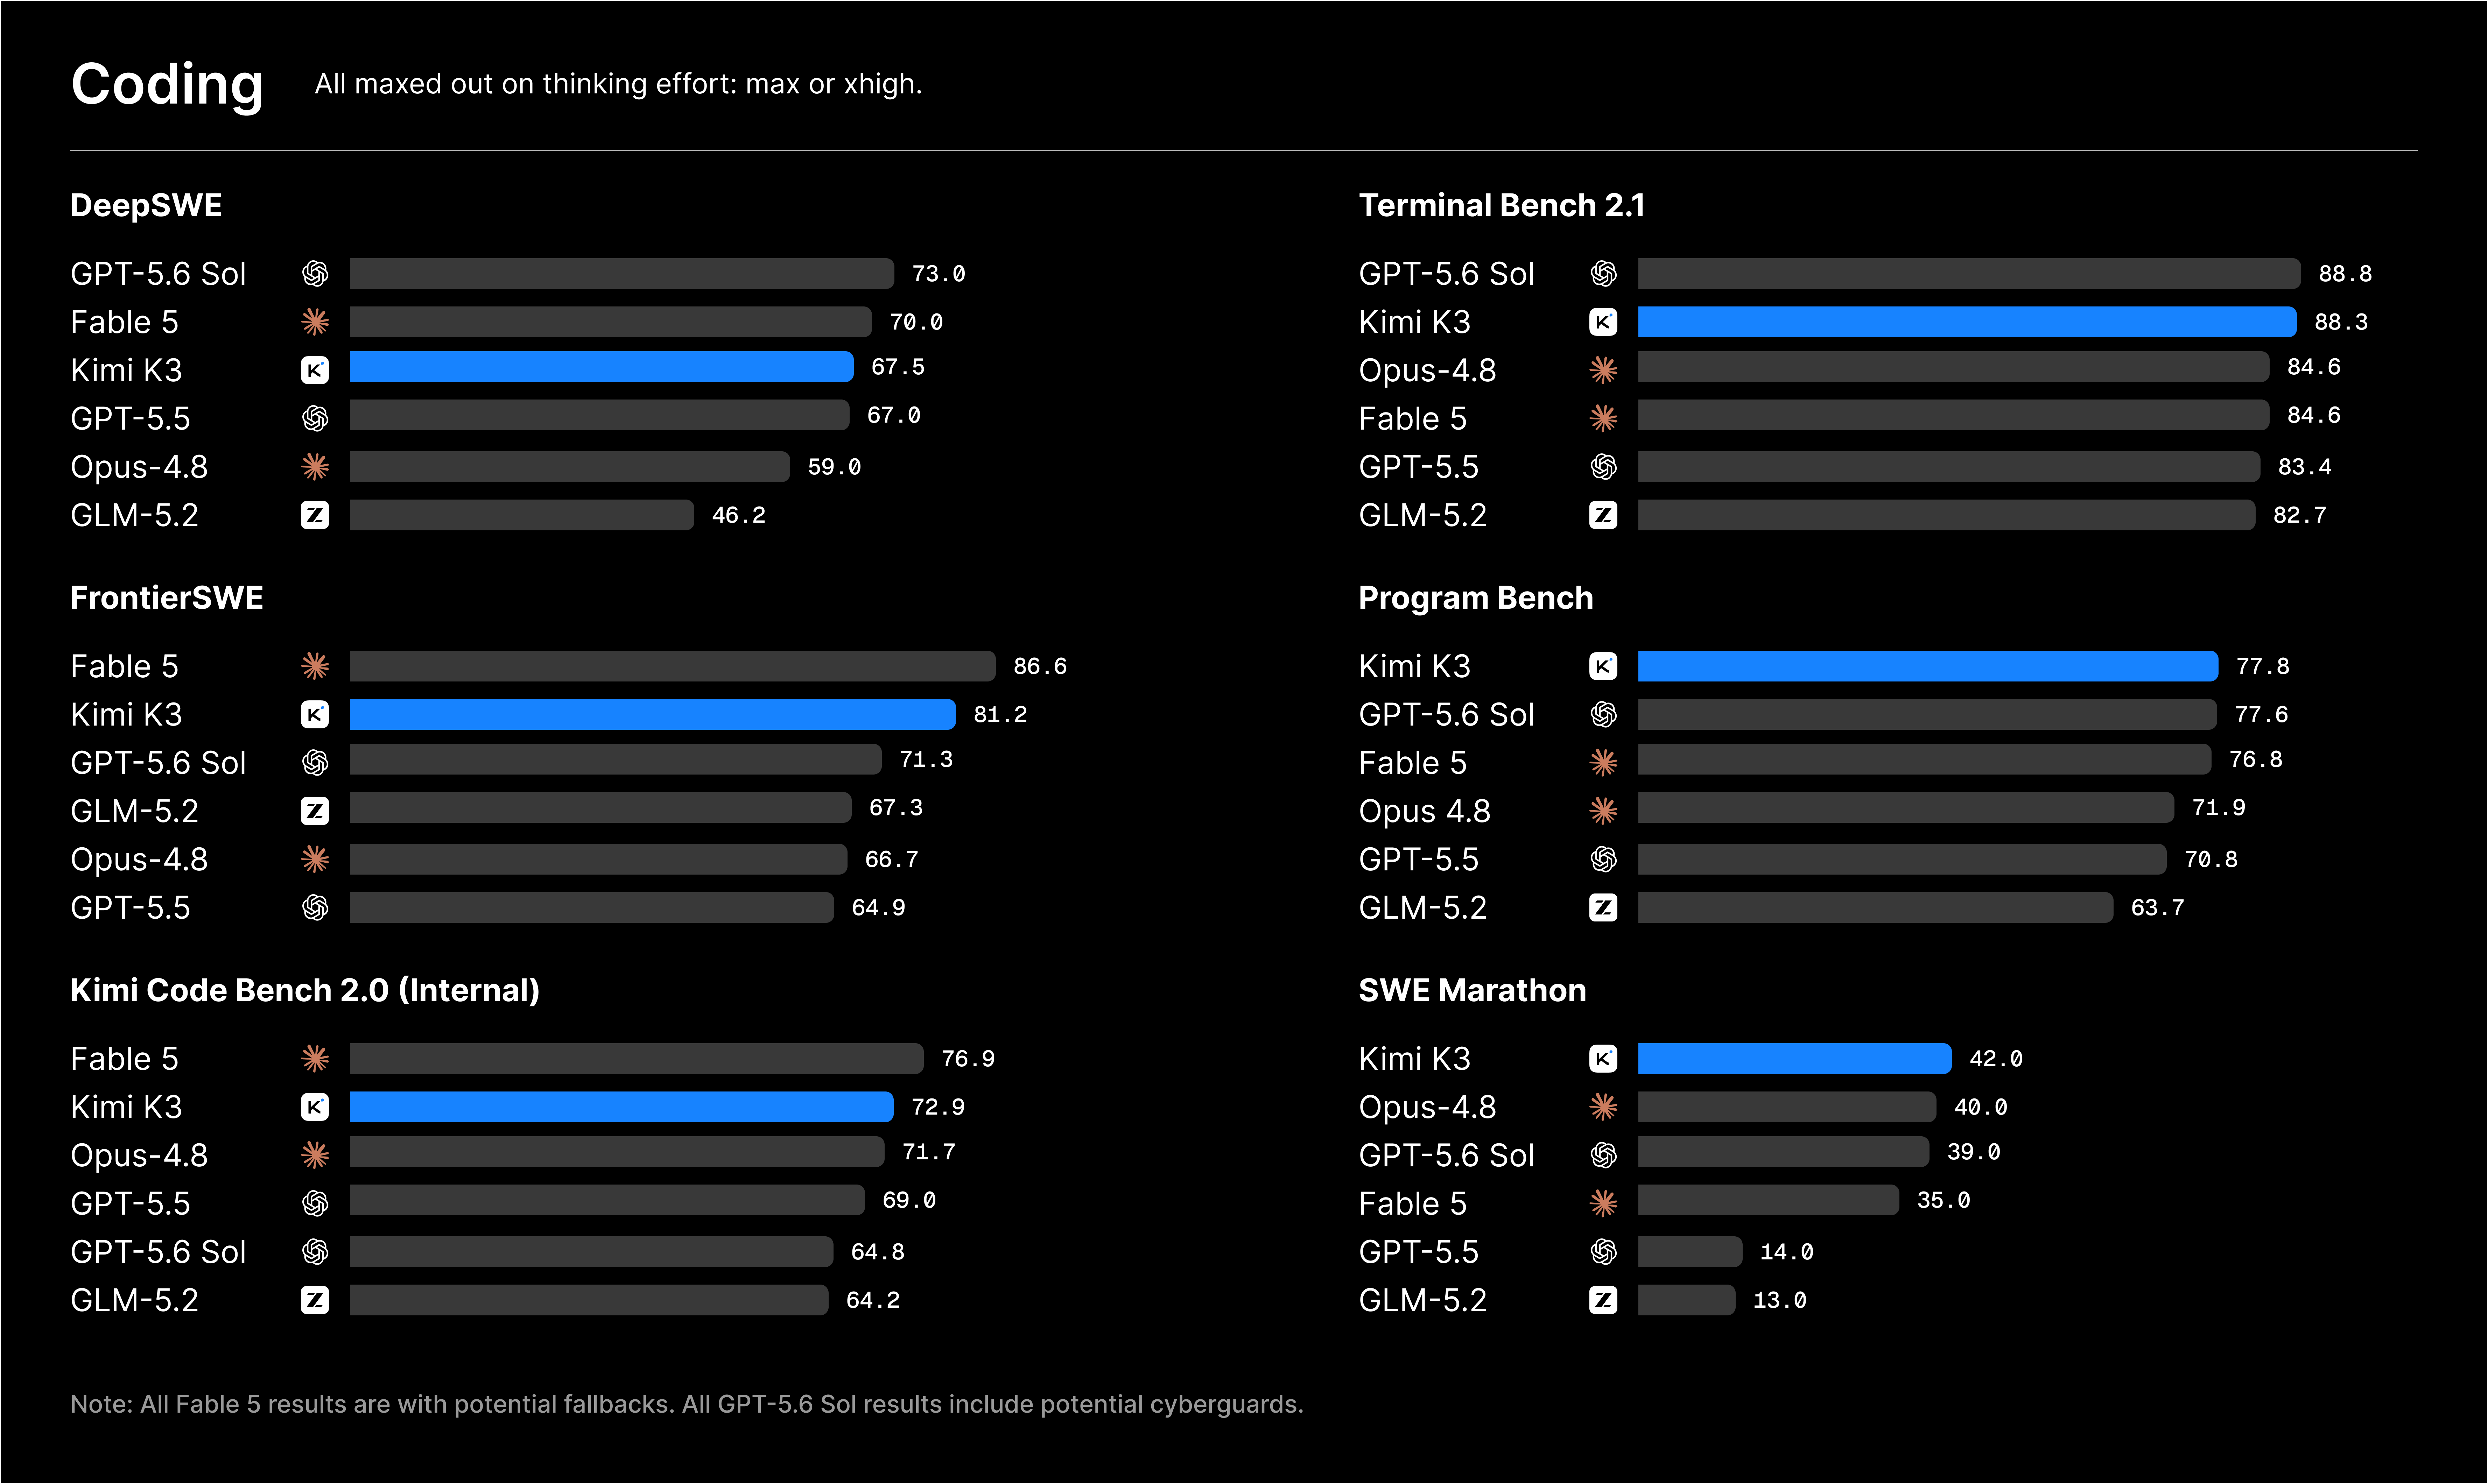
RECREATED 1:1 FROM THE OFFICIAL CHARTS ABOVE
Terminal-Bench 2.1
Program Bench — K3 #1
SWE Marathon — K3 #1
BrowseComp — K3 #1
SpreadsheetBench 2 — K3 #1
Automation Bench — K3 #1
Note (from Moonshot's own footnotes): Fable 5 results include potential fallback behavior; GPT-5.6 Sol results include potential cyberguards. BrowseComp uses context compaction at 300K; with a full 1M-token window K3 scores 90.4–91.2. Harnesses: KimiCode, Claude Code, or Codex per benchmark.
LMArena · Community-voted
Real users, blind votes. Kimi K3 jumped 17 places from K2.6 (#18 → #1) with a 76% pairwise win rate — vs 63% for Claude Fable 5 and 58% for GPT-5.6 Sol.
FRONTEND CODE ARENA — ELO
#1
Frontend Arena
76%
pairwise win rate
#9
Text Arena (was #38)
#1 IN 6 OF 7 FRONTEND DOMAINS
SOURCE: @ARENA ON X · JULY 16–17, 2026
Features
Six breakthroughs that make K3 the most exciting AI launch of 2026.
896 expert subnetworks with only 16 activated per token — massive capacity, efficient compute. The largest open-weight model ever released.
Feed entire codebases, full books, or dozens of reports in a single prompt. K3 remembers everything from start to finish.
Natively understands images, screenshots, diagrams and video — optimize frontend design, CAD, and UI from a single screenshot.
New KDA architecture delivers up to 6.3× faster decoding at million-token contexts and ~2.5× better scaling efficiency than K2.
Sustains multi-hour engineering sessions with minimal supervision — in testing it ran a 48-hour chip-design pipeline autonomously.
Full weights on Hugging Face under the Kimi K3 License: fine-tune and self-host for data privacy. Large API resellers need a separate agreement.
Under the hood
Nine of the past twelve months, Kimi models have set the upper bound of open-model sizes. K3 pushes it again — not with brute force, but with new attention and routing math.

A linear-attention variant that forms the efficient backbone for scaling — up to 6.3× faster decoding at million-token contexts, with a prefill-cache implementation contributed to vLLM.
Selectively retrieves representations across model depth instead of accumulating them uniformly — roughly +25% training efficiency at under 2% extra compute.
Extreme sparsity: each token activates just 16 of 896 experts (~104B of 2.8T parameters), keeping inference practical at 3T-class scale.
Derives expert allocation directly from router-score quantiles — loss-free load balancing with no auxiliary loss, no learning rate, no sensitive hyperparameter.
Extends the Muon optimizer by optimizing attention heads independently for more adaptive learning at scale.
Sigmoid Tanh Unit improves activation control; Gated MLA improves attention selectivity — together enabling stable 2.8T-scale training.
QAT from the SFT stage onward — MXFP4 weights with MXFP8 activations for broad hardware compatibility and cheap serving.
The combined structural changes convert compute into intelligence ~2.5× more effectively than the K2 generation.
FULL DETAILS IN THE K3 TECHNICAL REPORT · WEIGHTS RELEASED JULY 27, 2026 (KIMI K3 LICENSE)
Vision-in-the-loop · Game dev
K3 combines 3D reasoning, coding and native vision — it writes code, takes a screenshot of the result, sees what looks wrong, and iterates. Every frame below was generated by Kimi K3 from a single prompt, taken from Moonshot's launch blog.
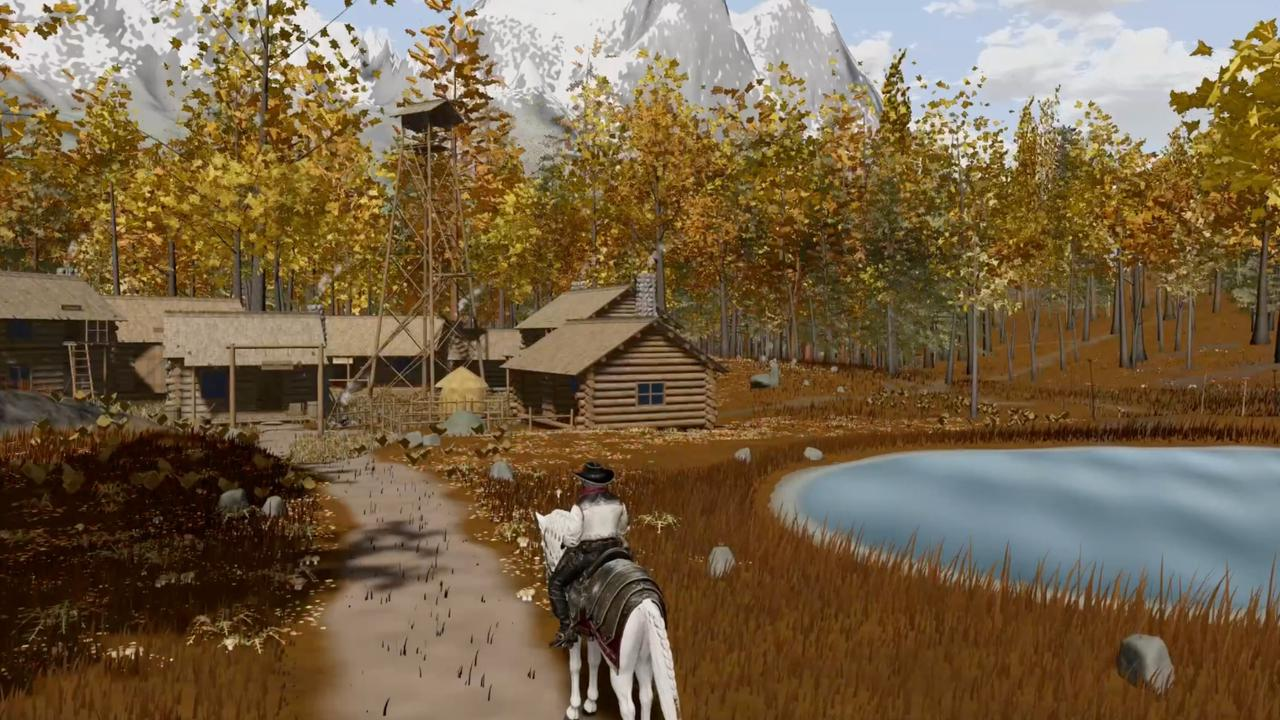
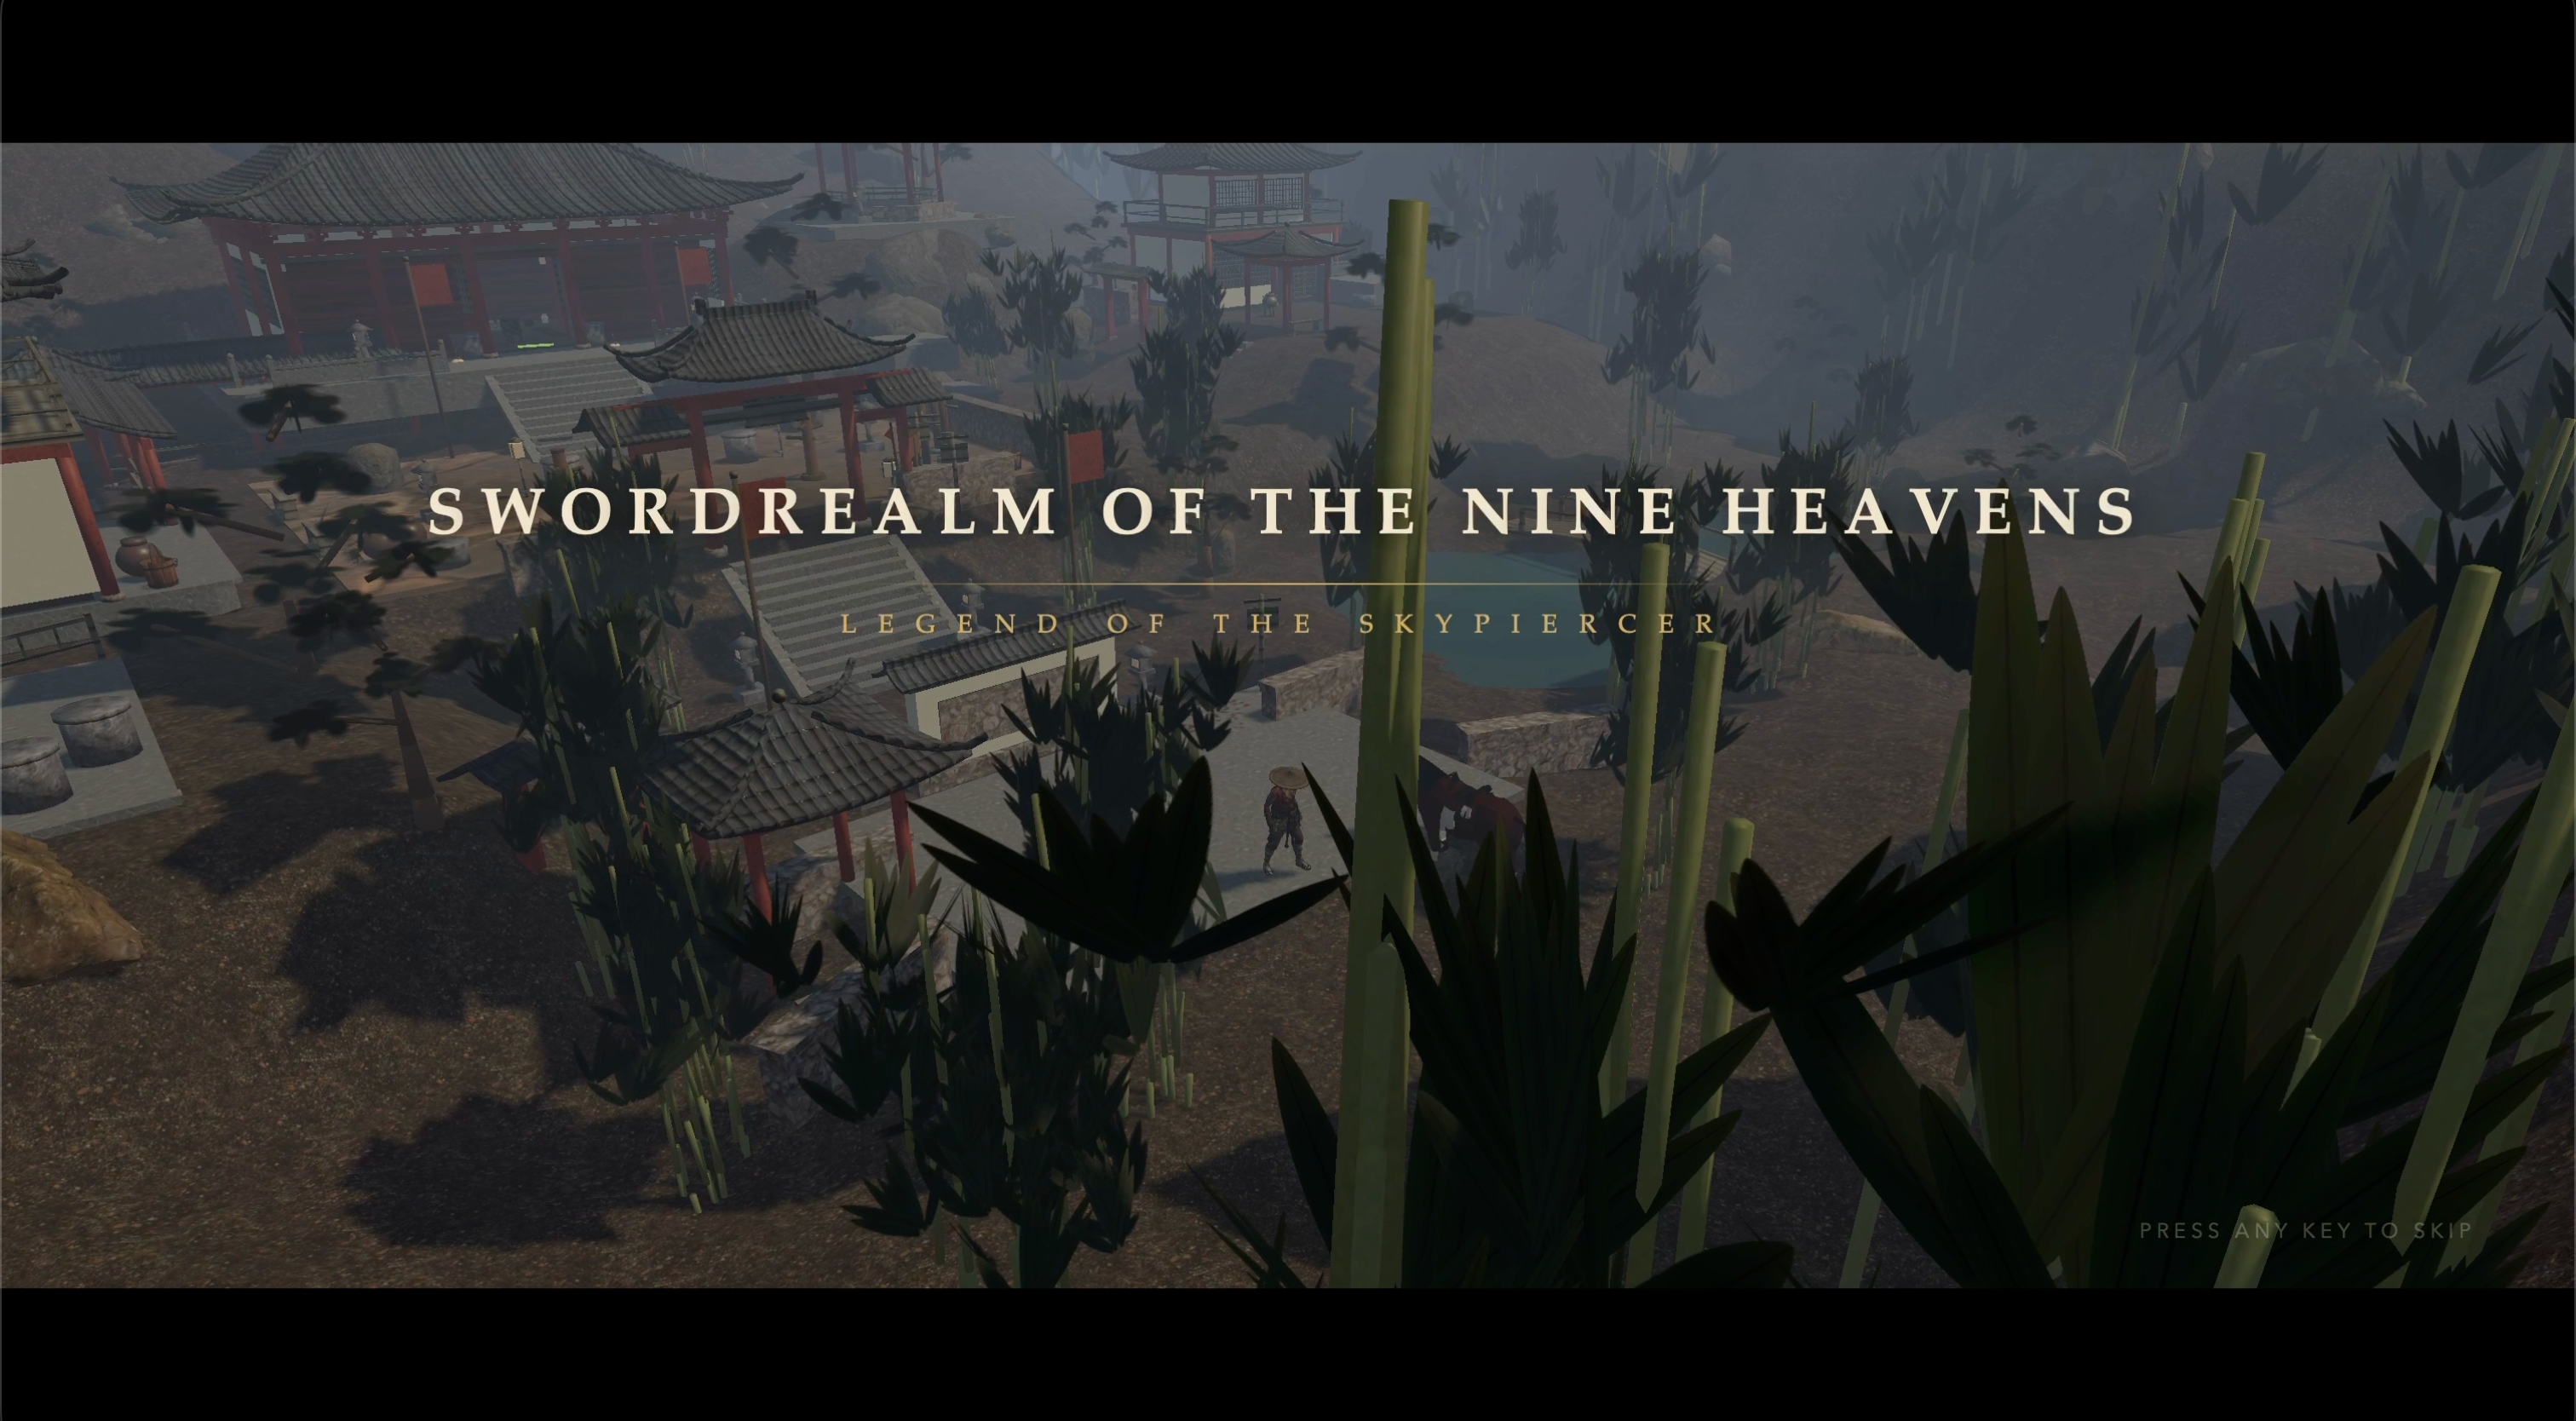
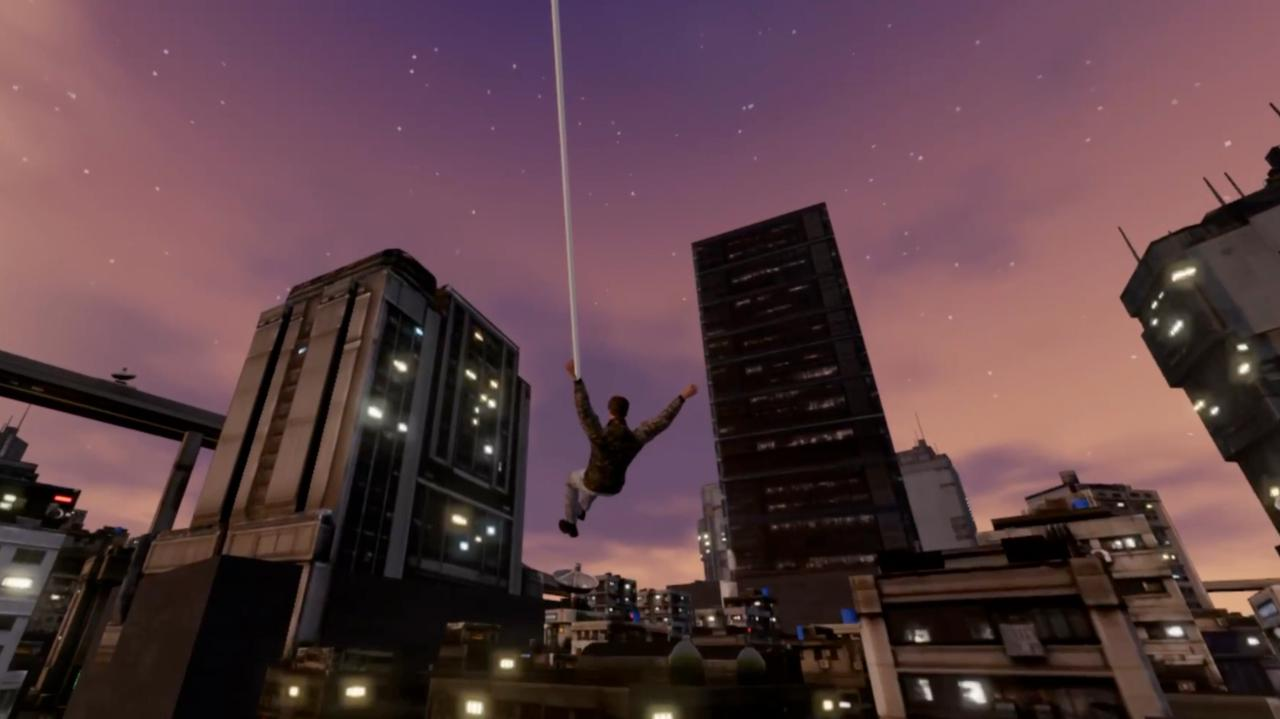
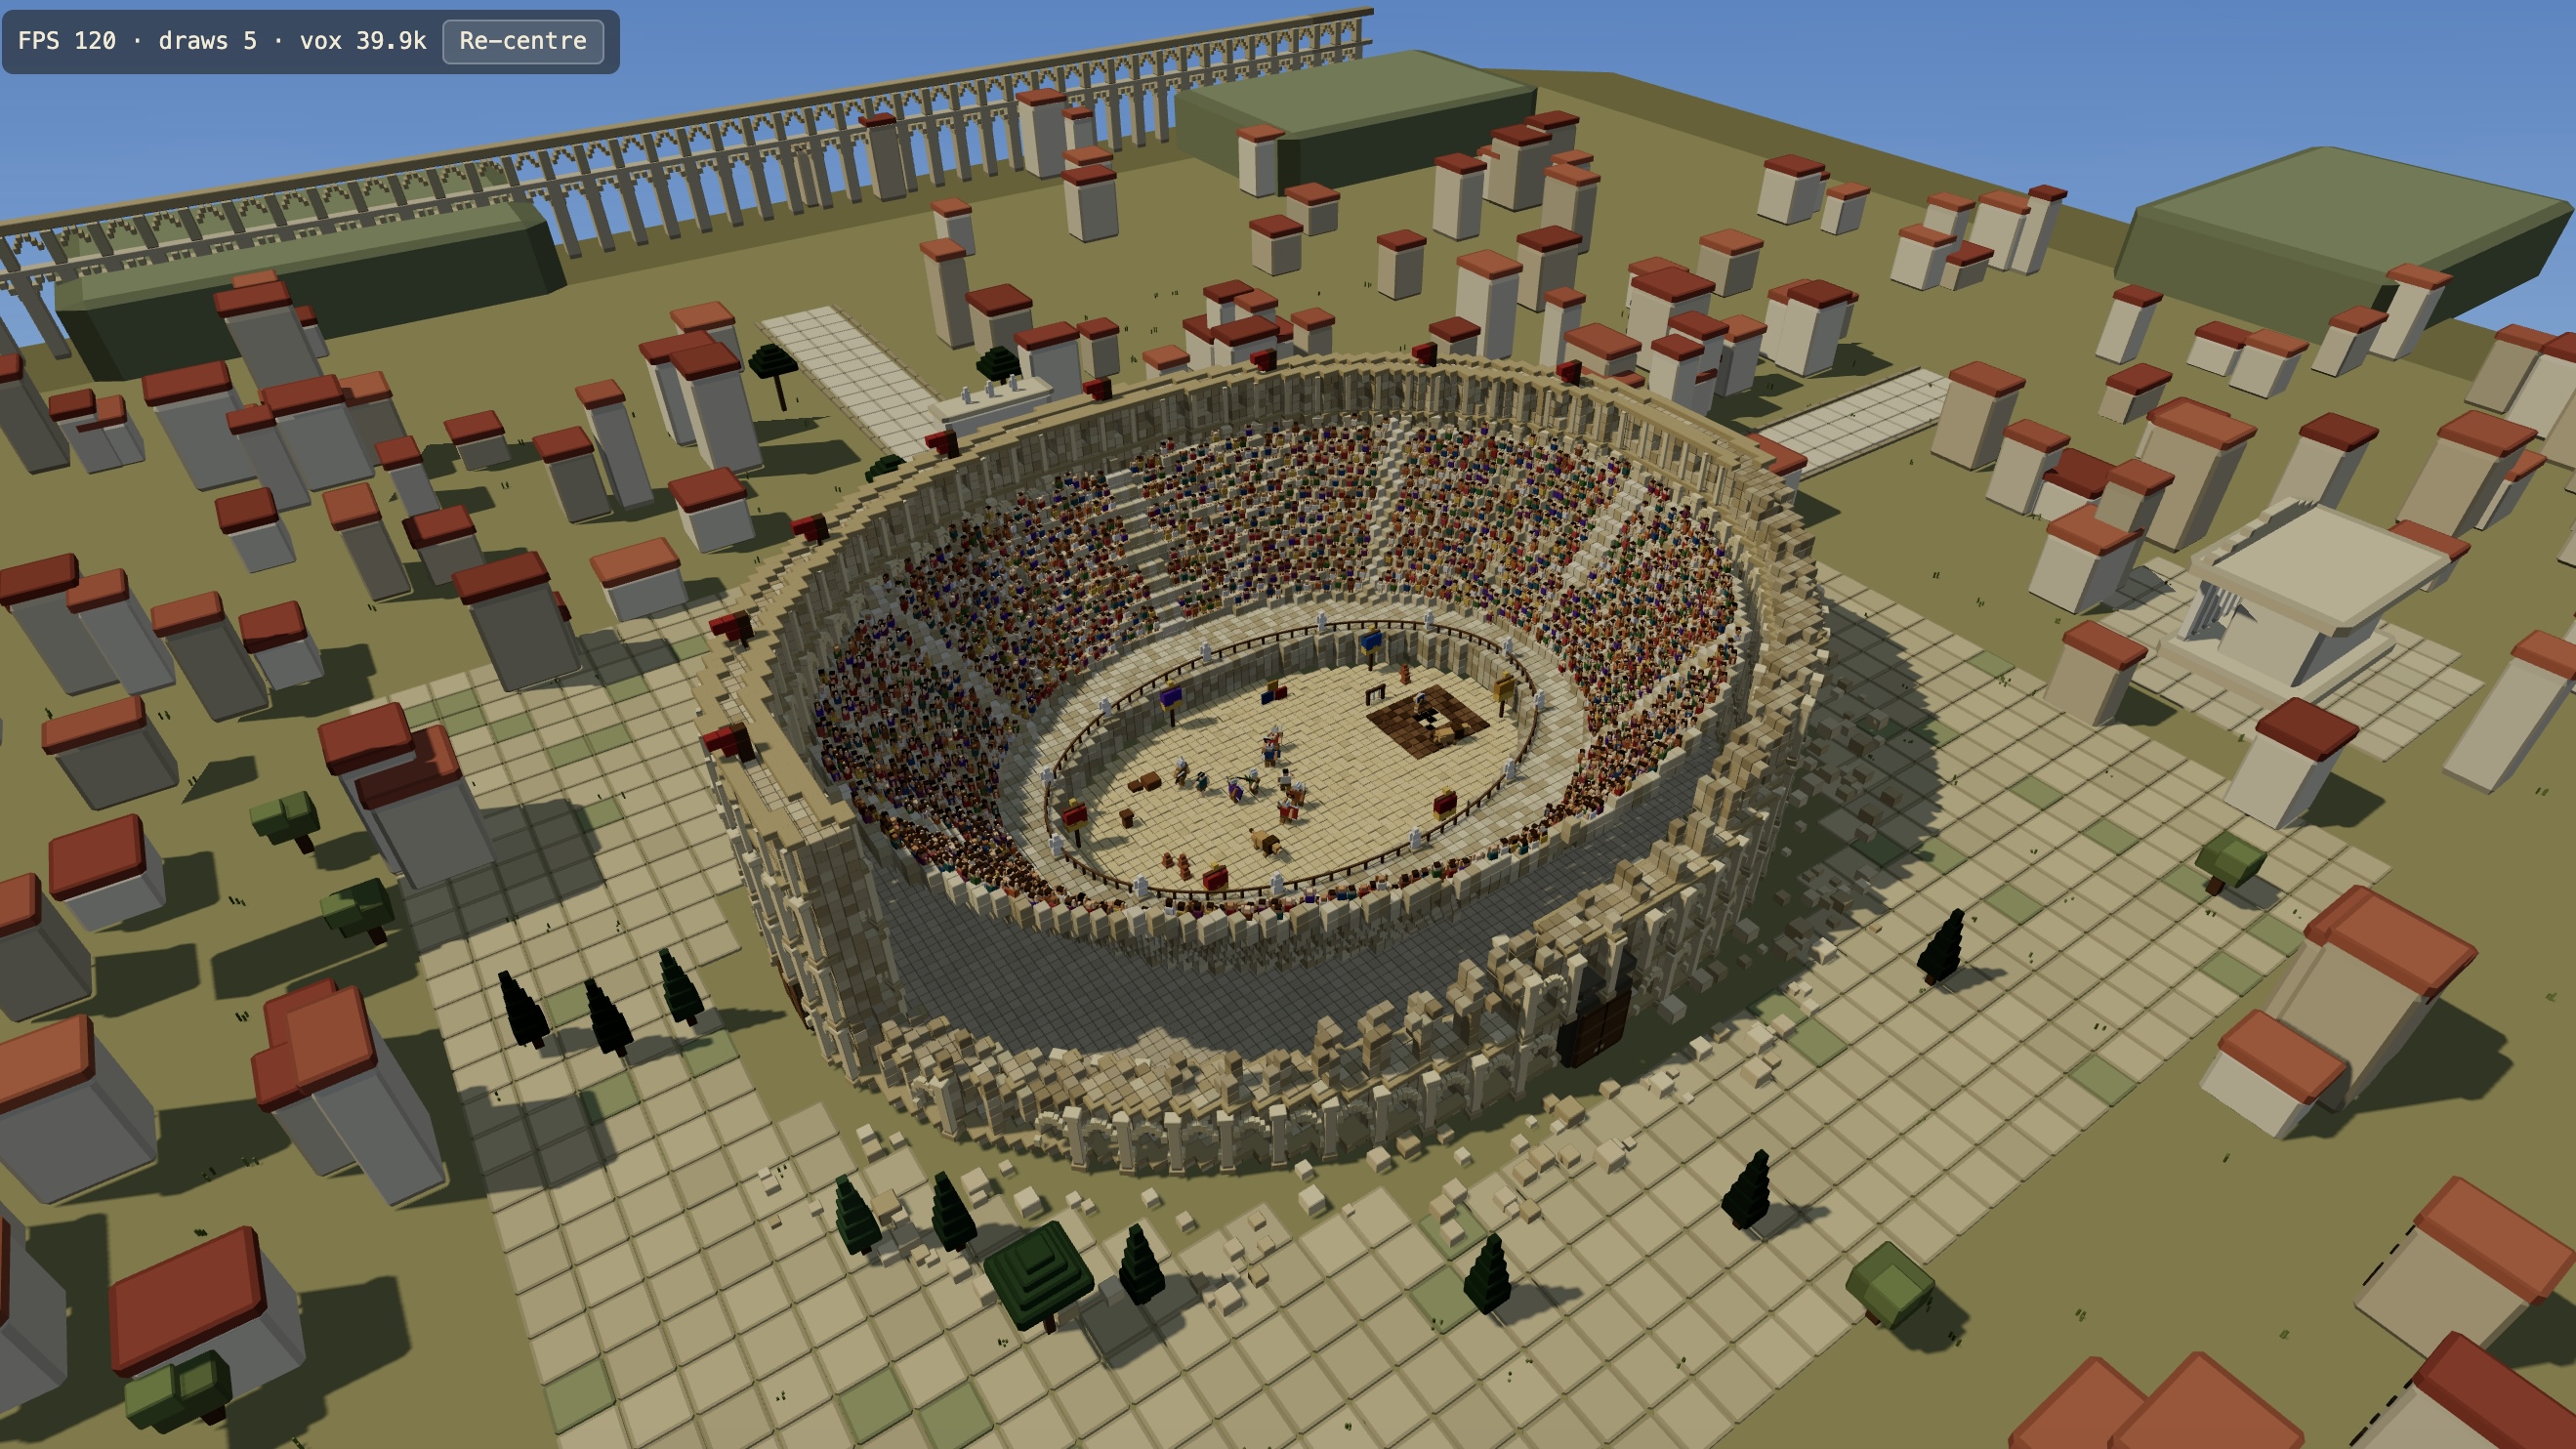
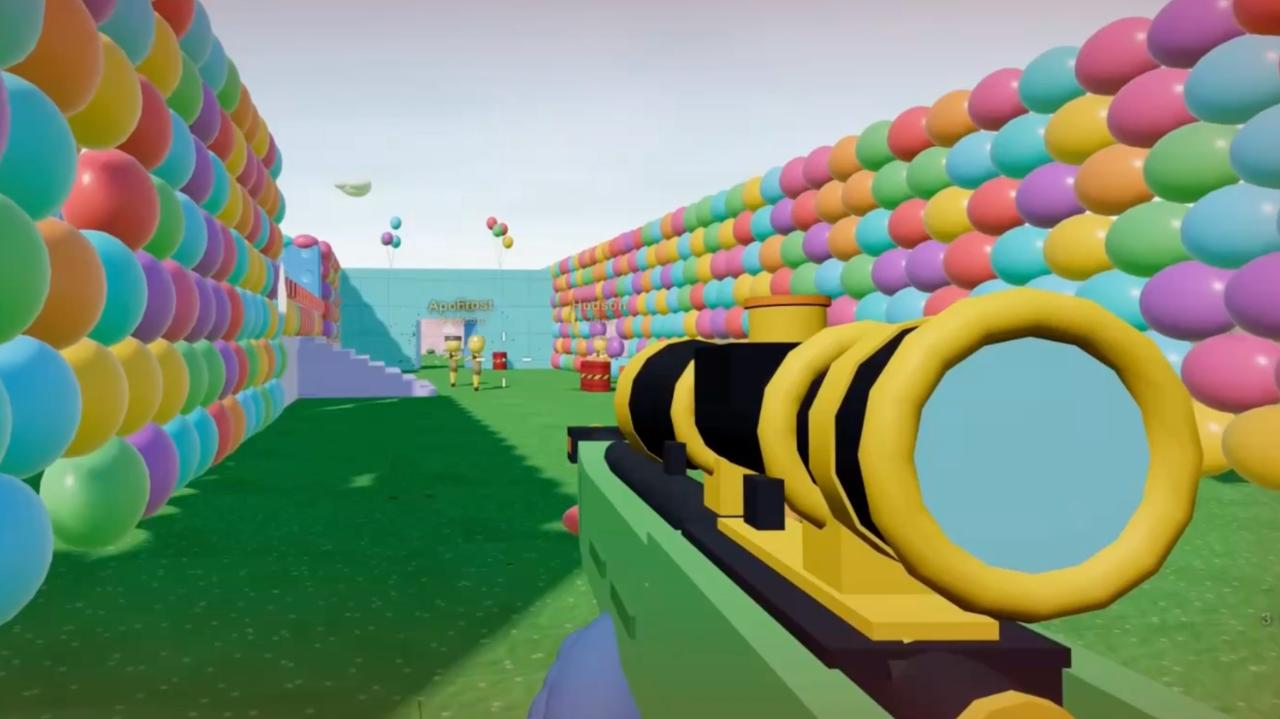
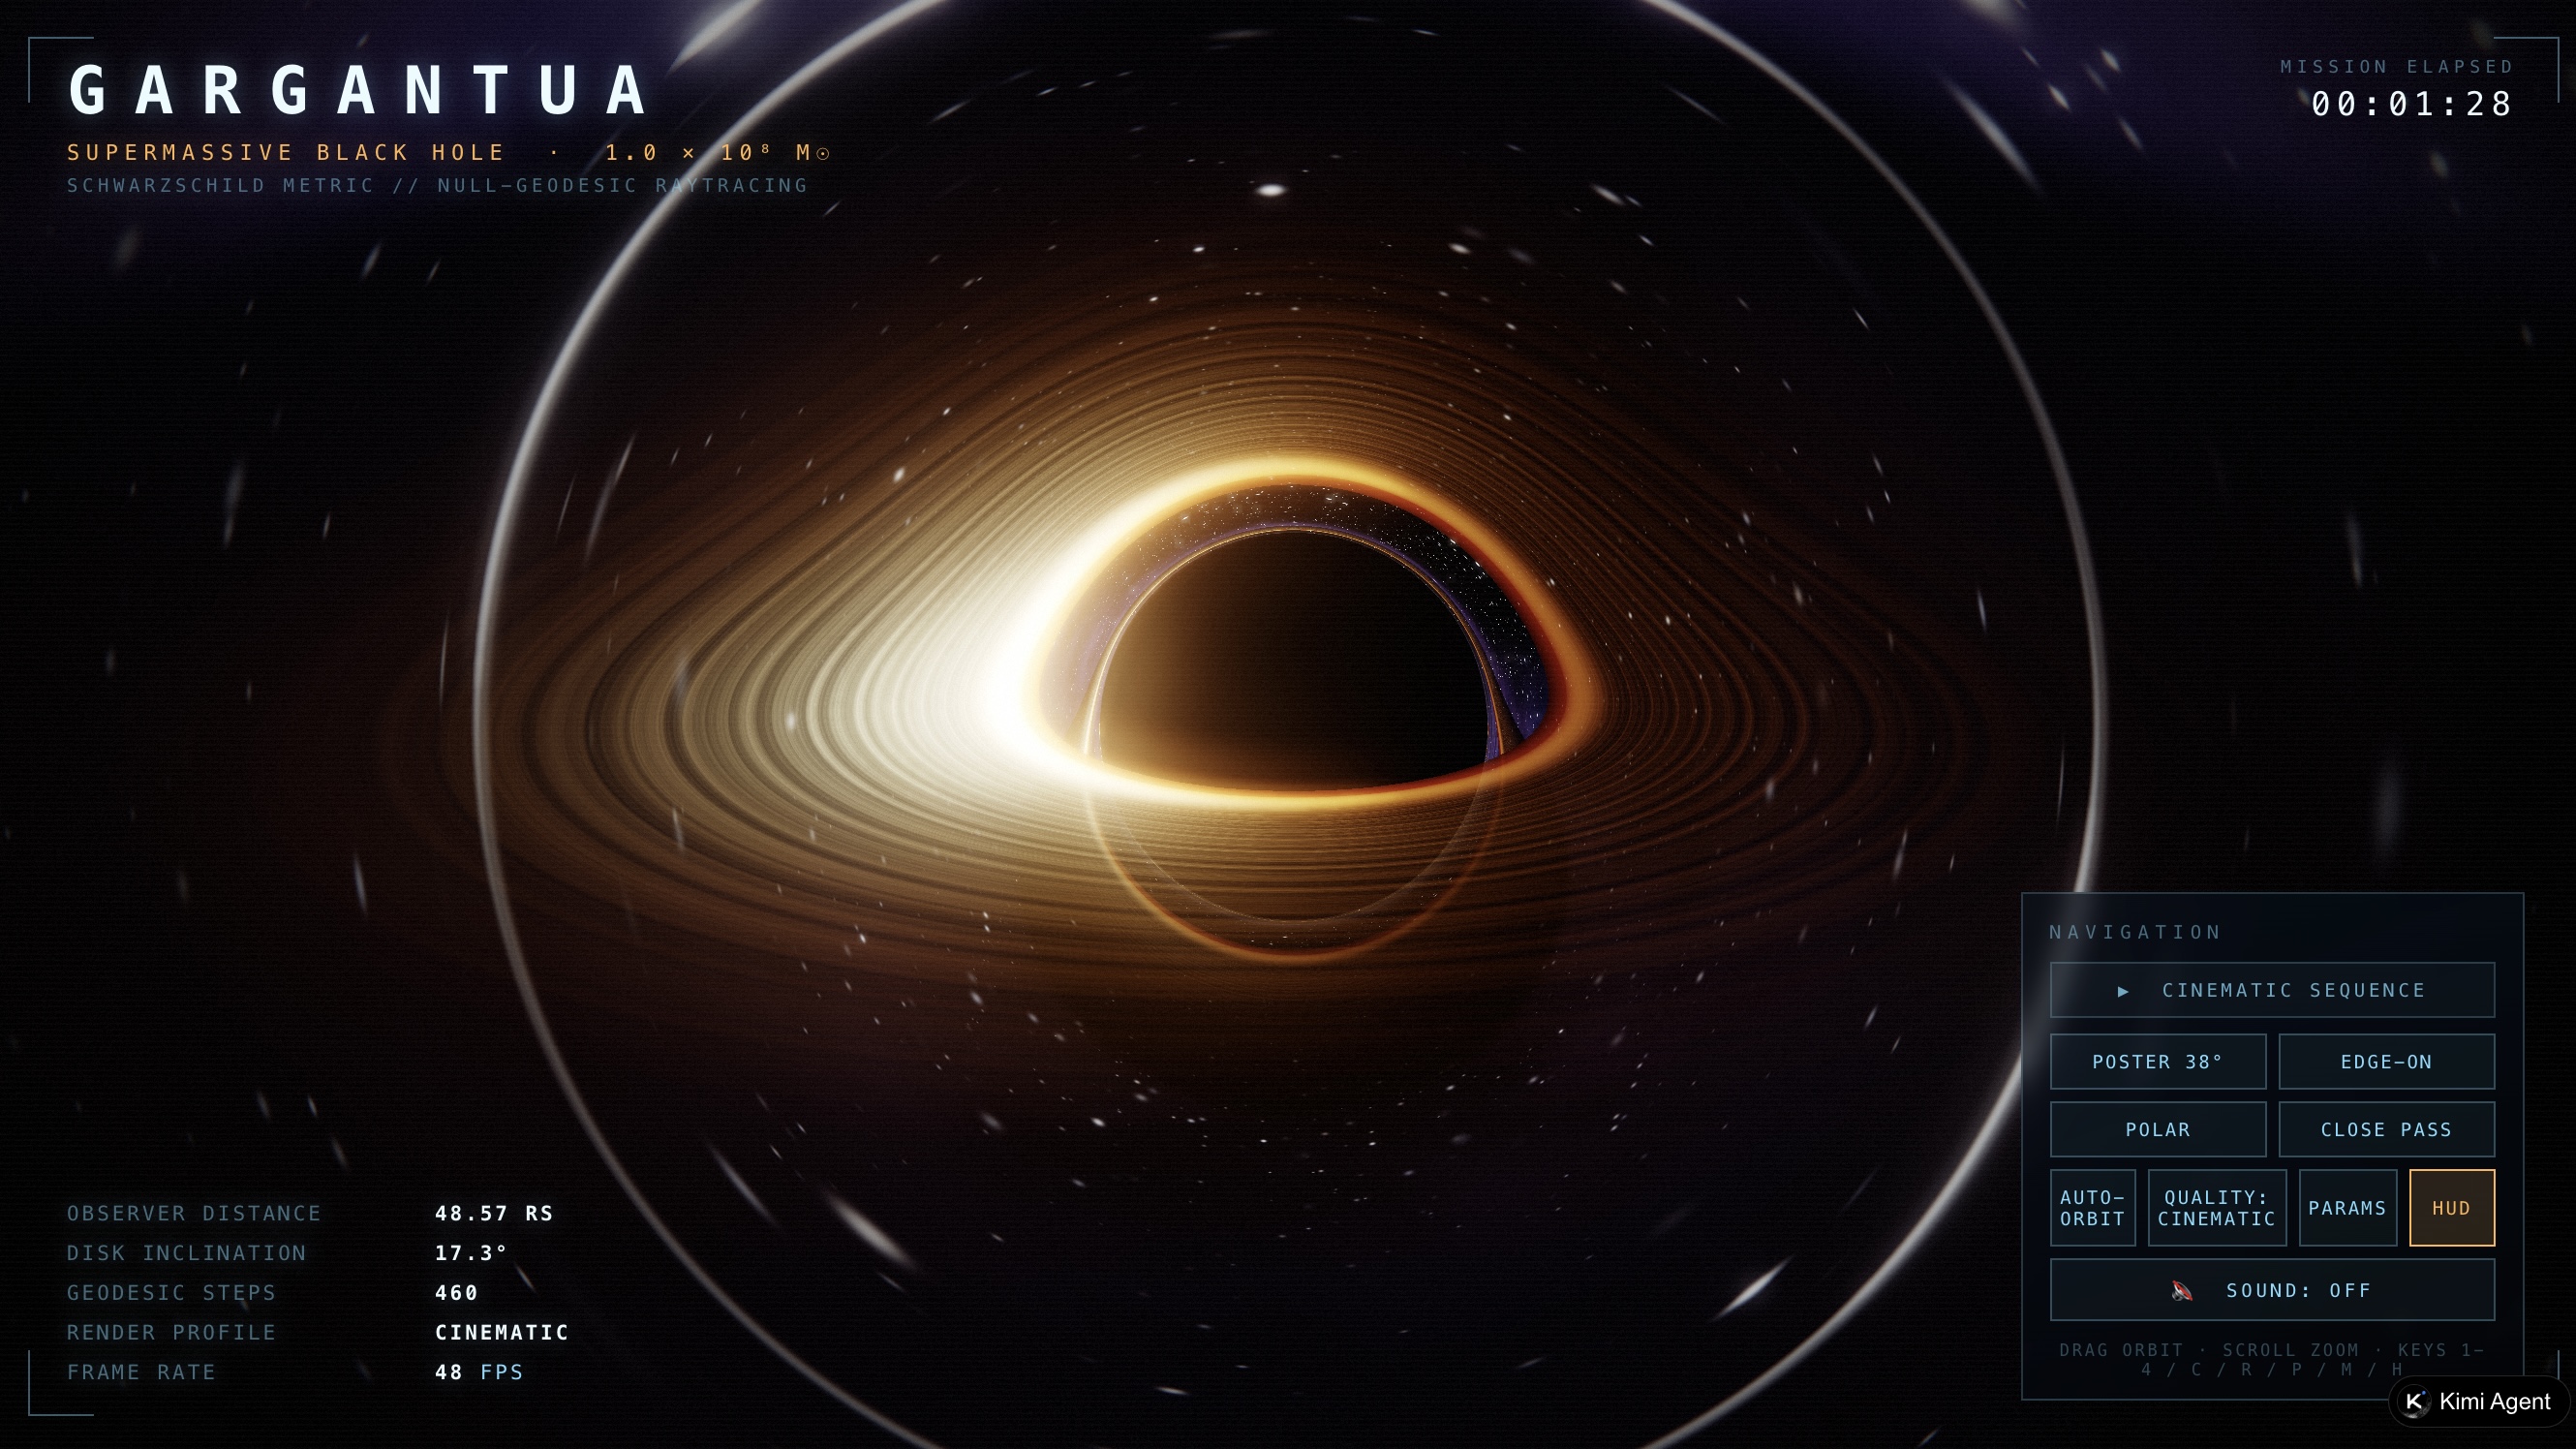
SCREENSHOTS: MOONSHOT AI — KIMI K3 GAME CASES
Kimi Work · Widgets & Dashboard
In Kimi Work, K3 generates interactive widgets — stock watchlists, Pomodoro timers, habit trackers, music players — that connect to local data and keep updating. Dashboard pins them into one persistent view built around your project.
Case studies · Long-horizon autonomy
01
K3 built a compact Triton-like compiler with its own tile-level IR over MLIR, optimization passes and a PTX codegen pipeline. It matches or beats Triton on supported roofline benchmarks and sustains end-to-end nanoGPT training.
DSL → IR → PTX → runtime
02
Given 24 hours in an identical sandbox to profile and rewrite GPU kernels (AttnRes, KDA, 512-head-dim MLA), K3 performed competitively with Claude Fable 5 and substantially outperformed Opus 4.8, GPT-5.6 Sol and GPT-5.5. An early K3 build already handled most of Moonshot's own kernel work.
NVIDIA H200 + alt-vendor GPGPU
03
To reproduce the I–Love–Q universal relations in computational astrophysics, K3 cross-validated 20+ papers, implemented the full numerical pipeline, evaluated 300+ equations of state, caught inconsistencies in published formulas, and wrote 3,000+ lines of Python plus an interactive dashboard.
Computational astrophysics
04
Through 120+ rounds of recursive self-improvement, K3 produced an interactive research site: 2.8k+ web searches, 1.1k+ terminal data pulls, 11k+ pages across 87 quarterly reports and 99 source PDFs — rendered as bespoke charts and animated diagrams.
Kimi Work · deep research
SOURCE: MOONSHOT AI — KIMI K3 LAUNCH BLOG
Kimi K3 vs Kimi K2
| Spec | Kimi K2 | Kimi K3 |
|---|---|---|
| Total parameters | 1.0T | 2.8T |
| Architecture | MLA MoE | KDA + AttnRes + Stable LatentMoE |
| Experts | 384 | 896 (16 active / token) |
| Context window | 256K tokens | 1,048,576 tokens |
| Vision / video input | — | Native |
| Long-context decode | baseline | up to 6.3× faster |
| Scaling efficiency | baseline | ~2.5× better |
| Frontend Code Arena | #18 (K2.6) | #1 |
| Weights license | Modified MIT | Kimi K3 License (custom) |
Read before use
Rare honesty for an AI launch, and exactly why this model is worth trusting. These are from the official launch post and independent testing.
01
K3 is trained with preserved thinking history. If the harness drops it — or you switch from another model mid-session — output quality can become unstable. Start a fresh K3 session instead.
02
Tuned for long-horizon tasks, K3 may make decisions on your behalf when intent is ambiguous. Set explicit boundaries in the system prompt or AGENTS.md.
03
Moonshot's own words: K3 "still trails the most powerful proprietary models, Claude Fable 5 and GPT-5.6 Sol" in overall user experience. It's the best open model — not the best model, period.
04
Independent tests measure ~62 output tokens/sec with ~2s TTFT — below the median for its price tier. Brilliant for long runs and batch work; less ideal for snappy chat UX.
Availability
Chat on iOS, Android, HarmonyOS, or the web. A free tier exists; confirmed K3 access (and 1M context on Pro) needs a paid plan.
Download Kimi K3 for PC — the desktop app (Windows / Apple silicon, v3.1.0+) for deep research, widgets and dashboards.
Terminal + IDE agent, included from the Plus plan up. Switch to K3 with the /model command.
OpenAI-compatible endpoint, also on Amazon Bedrock and 15+ providers. Create a Kimi API key and select kimi-k3. Unlocks after a $1 top-up.
API platform →from openai import OpenAI
client = OpenAI(
api_key="YOUR_MOONSHOT_API_KEY",
base_url="https://api.moonshot.ai/v1",
)
resp = client.chat.completions.create(
model="kimi-k3",
messages=[{"role": "user", "content": "Refactor this repo"}],
reasoning_effort="high", # low / high / max
)Pricing
| Kimi K3 API | Per 1M tokens |
|---|---|
| Cache-hit input | $0.30 |
| Cache-miss input | $3.00 |
| Output | $15.00 |
| Avg. cost per benchmark task | $0.94 |
Mooncake disaggregated inference · >90% cache-hit rate in coding workloads
Latest guides

Kimi K3 vs Claude Opus 5.5: $3/$15 vs $4/$20 pricing, independent benchmarks, per-task costs, worked examples for coding agents, RAG and batch, when to switch.
Kimi K3 vs GPT-6 Astra: $3/$15 vs $10/$50 pricing, the 272K surcharge, independent benchmark scores, privacy, open weights, and when switching actually pays.
Kimi K3 vs Claude Fable 5.1: $3/$15 vs $10/$50, four worked cost examples, independent benchmarks, the Opus 5.5 twist, and a clear guide on when to switch.
Kimi K2.8 Preview now powers kimi-for-coding in Kimi Code with 1M context on every coding plan. What's confirmed, who gets it, API status, and when to pick K3.
What the Kimi K3 License allows: commercial use, fine-tuning, the $20M Model-as-a-Service clause and attribution rules, compared with K2, Llama and Qwen.
Set up Kimi Code CLI with K3: install per OS, login, config.toml, effort levels, MCP, IDEs, Claude Code/Cline setup, plan prices, and when K2.7 or K2.8 wins.
FAQ
Kimi K3 is Moonshot AI's flagship model launched July 16, 2026 — the world's first open 3T-class model. It has 2.8 trillion parameters in a mixture-of-experts design (16 of 896 experts active per token), a 1,048,576-token context window, native image/video understanding, and is built on the new Kimi Delta Attention and Attention Residuals architecture.
Kimi K3 officially launched on July 16, 2026, and is available today on Kimi.com, Kimi Work, Kimi Code, and the Kimi API. Some users search for it as "Kimi 3.0" — Moonshot's official name is Kimi K3. The full open-weight release (model weights + technical report) followed on July 27, 2026.
Kimi K3 specs: 2.8T total parameters (Stable LatentMoE, 16 of 896 experts active per token), 1M-token context window, native image/video understanding, Kimi Delta Attention + Attention Residuals architecture, Gated MLA, MXFP4 weights with MXFP8 activations, about 104B active parameters per token, low / high / max thinking effort, and the custom Kimi K3 open-weight license.
No — k3-kimi.com is an independent fan-made guide. The official Kimi AI website is kimi.com, where you can log in (Kimi login) and use K3 on a paid plan. Official docs live on Moonshot's Kimi API Platform. We just track benchmarks, pricing, and news.
On desktop, download the Kimi Work app (version 3.1.0 or later) for Windows or Apple silicon Mac from the official Kimi site — K3 is built in. Alternatively use kimi.com in any browser with no download, or run Kimi Code in your terminal and pick Kimi K3 with the /model command. Mobile apps are on iOS, Android, and HarmonyOS.
The full Kimi K3 weights have been on Hugging Face (moonshotai/Kimi-K3) since July 27, 2026 under the Kimi K3 License, alongside the technical report. They are about 1.56TB in MXFP4 — but note a 2.8T model needs supernode-class infrastructure (64+ accelerators recommended), so most users should stick to the app or API.
API pricing: $0.30 per million tokens for cache-hit input, $3.00/M for cache-miss input, and $15.00/M for output, with a 90%+ cache hit rate in coding workloads. Cache writes cost $3/M (5-minute) or $6/M (1-hour). In the app, confirmed K3 access needs a paid plan: Plus (¥99/month) for K3 at 256K context, Pro (¥199/month) for 1M.
Sign up on Moonshot's Kimi API Platform, create an API key, and select the kimi-k3 model. The official docs on the platform cover authentication, endpoints, and the KDA prefill-cache behavior. In the Kimi Code CLI, run /model and choose Kimi K3 — no manual key needed if you're logged into your Kimi account.
Our take: yes for long-horizon coding, research, and agentic work. It's #1 on Frontend Code Arena, beats Claude Opus 4.8 and GPT-5.5 on most coding benchmarks, handles 1M-token contexts, and costs about half as much. Weaknesses: still trails Claude Fable 5 and GPT-5.6 Sol in overall polish, and output speed (~35 tok/s on Moonshot's endpoint) favors long runs over snappy chat.
Partly. The Kimi app has a free tier, but Moonshot lists K3 access only for paid plans (Plus and above) and does not say which model free users get. The API is paid ($0.30/M cached input, $3/M input, $15/M output) and unlocks after a $1 top-up. The open weights are free to download under the Kimi K3 License.
On Moonshot's launch suite, K3 ranks #1 on Program Bench (77.8), SWE Marathon (42.0), SpreadsheetBench 2 (34.8), Automation Bench (30.8) and BrowseComp (91.2), and #2 on Terminal-Bench 2.1 (88.3 vs Sol's 88.8). On the community-voted LMArena it is #1 in Frontend Code with a 76% win rate. Artificial Analysis scored it 57 at launch; on the current index (v4.3.2) it scores 44, #3 among large open-weight models. Moonshot itself says it still trails Fable 5 and GPT-5.6 Sol overall.
Nearly everything: 2.8T vs 1.0T parameters, 896 vs 384 experts, 1M vs 256K context, native vision for the first time, the new KDA + Attention Residuals architecture (~2.5× scaling efficiency, up to 6.3× faster long-context decoding), and a jump from #18 to #1 on Frontend Code Arena.
Open weights, yes: released July 27, 2026 under the Kimi K3 License (not an OSI open-source license). Realistically, a 2.8T-parameter model needs serious infrastructure — Moonshot recommends supernode deployments with 64+ accelerators. Most people should use the app or API.
Per Moonshot: don't switch models mid-session (thinking-history sensitivity), it can be overly proactive on ambiguous tasks, and it still trails Fable 5 / GPT-5.6 Sol in overall UX. Independent tests also note slower output speed (~35 tok/s) — better for long runs than snappy chat.
Long-horizon agentic work: it built playable games from single prompts, designed a working chip autonomously in 48 hours, wrote a GPU compiler (MiniTriton) from scratch that rivals Triton, reproduced astrophysics research in 2 hours that typically takes 1–2 weeks, and produces interactive research reports and video edits in Kimi Work.